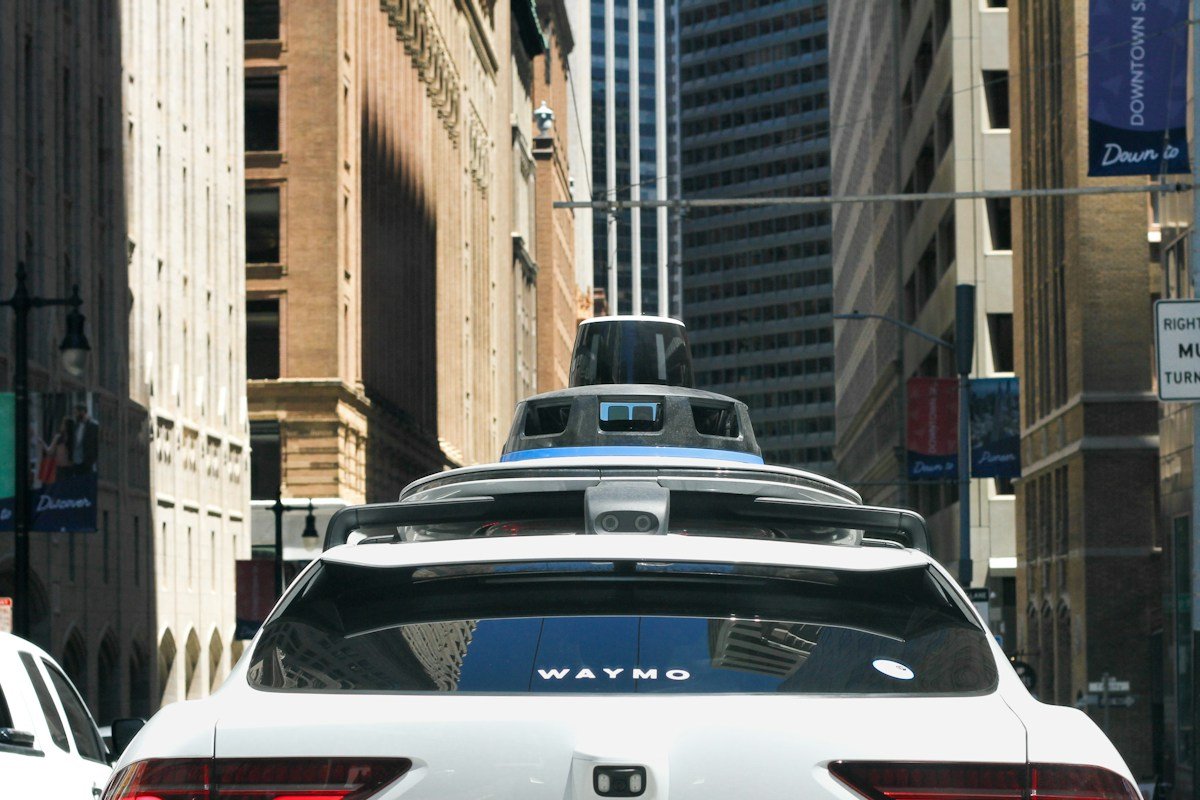

Edge computing architecture represents the critical foundational infrastructure enabling the operation, safety, and scalability of modern autonomous systems. Across autonomous electric vehicles, industrial robotic swarms, uncrewed aerial systems, and automated logistics hubs, autonomous agents cannot tolerate the transmission latencies, bandwidth costs, and network dropouts inherent to centralized cloud computing. When an autonomous vehicle traveling at highway speeds encounters an unexpected pedestrian or road obstacle, the computational decision loop governing perception, path planning, and physical actuation must execute deterministically within ten to twenty milliseconds.
Relying on backhaul telecommunications to transmit multi-gigabit raw sensor streams across cellular base stations to remote hyperscale cloud datacenters introduces unacceptable round-trip latencies of fifty to two hundred milliseconds, alongside catastrophic vulnerabilities to packet loss and telecommunication outages. Autonomy demands that intelligence migrate from centralized server farms directly to the logical and physical periphery: the operational network edge. By deploying high-performance heterogeneous compute silicon directly onboard autonomous platforms and across local edge micro-datacenters, edge computing guarantees sub-millisecond local inference, ensures deterministic physical control, and safeguards operational continuity during complete network disconnections.
Modern edge architectures for autonomous systems transcend simple localized computation; they encompass a sophisticated, multi-tiered computational fabric. This fabric spans onboard System-on-Chip (SoC) accelerators executing quantized neural networks, vehicle-to-everything (V2X) wireless communication links, distributed peer-to-peer mesh networking protocols, and collaborative multi-access edge computing (MEC) nodes. Together, these layers orchestrate continuous sensor fusion, real-time SLAM (Simultaneous Localization and Mapping), cooperative swarm maneuvers, and fault-tolerant decentralized consensus under extreme physical constraints.
This comprehensive systems engineering manual delivers an authoritative, technical masterclass in edge computing architectures for autonomous platforms. Designed for robotics architects, embedded systems engineers, and distributed systems specialists, this guide explores the hardware acceleration paradigms, low-latency neural inference pipelines, real-time operating system (RTOS) determinism, vehicle-to-vehicle mesh networking protocols, and edge-to-cloud synchronization frameworks necessary to build resilient, next-generation autonomous operations.
Computational Latency Budgets and Deterministic Safety Bounds in Autonomy
The architectural design of an autonomous edge system is dictated fundamentally by the strict constraints of the Physical Control Loop. Unlike conventional consumer software where latency impacts user experience, in robotics and autonomous vehicles, latency directly governs physical kinetic safety and dynamic stability.
Consider an autonomous vehicle operating at seventy miles per hour (approximately thirty-one meters per second). In the domain of safety-critical motion planning, the total latency budget—encompassing photonic sensor photon capture, LiDAR point-cloud ingestion, neural network inference, kinematic trajectory generation, CAN bus signal serialization, and hydraulic brake actuator piston pressurization—cannot exceed fifty milliseconds. Every ten milliseconds of computational delay translates directly to approximately one foot of unguided physical vehicle travel. A system that introduces a hundred-millisecond cloud round-trip delay allows a vehicle to travel ten feet blindly before initiating evasive steering maneuvers.
To guarantee physical safety, autonomous edge systems operate under strict Real-Time Operating System (RTOS) scheduling. General-purpose operating systems (such as standard enterprise Linux or Windows) prioritize average-case throughput; their task schedulers and memory managers introduce non-deterministic latency spikes caused by interrupt handling, page faults, and kernel lock contentions. In contrast, safety-critical autonomous nodes utilize hard real-time environments (such as QNX Neutrino, VxWorks, or Linux patched with PREEMPT_RT) where worst-case execution time (WCET) is mathematically bounded.
In hard real-time architectures, tasks are assigned strict pre-emptive priorities using Rate-Monotonic or Earliest-Deadline-First scheduling algorithms. Safety-critical sensor polling and actuator output loops execute deterministically within dedicated clock cycles, guaranteeing that even under peak computational load or memory pressure, emergency collision-avoidance subroutines execute without jitter.
Heterogeneous Compute Silicon: ASICs, NPUs, GPUs, and FPGA Co-Processors
Executing deep perception and spatial localization neural networks on edge platforms requires extraordinary computational density balanced against severe Thermal Design Power (TDP) and electrical energy constraints. An autonomous platform operating on battery reserves cannot support kilowatt enterprise server racks; it demands heterogeneous computing architectures that deliver hundreds of trillions of operations per second (TOPS) within a power envelope of thirty to two hundred watts.
Heterogeneous edge architectures allocate computational workloads to specialized silicon engines optimized for distinct mathematical topologies. General-purpose multi-core ARM or RISC-V CPUs manage system orchestration, operating system housekeeping, high-level mission logic, and deterministic CAN/Ethernet network communication. However, dense tensor operations are offloaded entirely to dedicated parallel accelerators.
Embedded GPUs (Graphics Processing Units), featuring thousands of SIMD (Single Instruction, Multiple Data) processing cores and specialized tensor cores, excel at parallel matrix multiplication, executing convolutional backbones and transformer attention layers for camera perception pipelines. Field-Programmable Gate Arrays (FPGAs) provide reconfigurable hardware logic, enabling customized, cycle-accurate processing pipelines for raw sensor deserialization and low-latency LiDAR point-cloud voxelization without CPU mediation.
Neural Processing Units (NPUs) and deep learning ASICs (Application-Specific Integrated Circuits) represent the pinnacle of energy efficiency. By implementing systolic array architectures—where computational processing elements pass data directly to adjacent elements without repeatedly reading from and writing to external DRAM—NPUs achieve computational efficiencies exceeding ten to twenty TOPS per watt, enabling continuous real-time neural vision inference on low-power aerial drones and autonomous mobile robots (AMRs).
Neural Model Optimization: Quantization, Pruning, and Knowledge Distillation
Deploying modern deep learning architectures—such as multi-camera vision foundation models and Bird’s-Eye-View (BEV) perception networks—onto edge hardware requires aggressive mathematical model compression. Uncompressed neural models, trained in cloud datacenters utilizing single-precision floating-point (FP32) arithmetic, demand gigabytes of memory storage and hundreds of memory-bandwidth-choking memory fetches per frame.
Quantization is the primary mathematical mechanism for accelerating edge inference. By mapping continuous 32-bit floating-point weights and activation tensors onto discrete, low-bit integer representations (INT8 or INT4), quantization reduces the model memory footprint by seventy-five percent and dramatically accelerates execution speed, as modern NPU tensor engines process integer multiply-accumulate (MAC) operations four to eight times faster than floating-point math. Quantization-Aware Training (QAT) simulates rounding and clamping errors during model fine-tuning, preserving full model accuracy even when compressing complex multi-head attention weights down to 8-bit precision.
Structured weight pruning complements quantization by identifying and eliminating non-essential synaptic connections within neural layers. By pruning entire convolutional filters or attention heads that contribute minimally to feature extraction, pruning reduces the floating-point operation (FLOP) count while preserving dense, hardware-friendly matrix geometry that avoids the pipeline stalls associated with unstructured sparse matrices.
Knowledge distillation transfers the rich feature representations learned by massive, compute-heavy cloud teacher models into compact, lightweight student models optimized for edge silicon. The student network is trained to mimic the softmax probability distributions and intermediate feature maps of the teacher model, enabling a sixty-million-parameter edge vision model to achieve perception accuracy comparable to a multi-billion-parameter cloud architecture.
Multi-Modal Sensor Ingestion and Real-Time Hardware-Synchronized Fusion
Autonomous edge perception relies upon the integration of complementary, physically diverse sensing modalities: high-resolution CMOS cameras, LiDAR (Light Detection and Ranging) scanners, millimeter-wave radar units, ultrasonic transducers, and tactical-grade Inertial Measurement Units (IMUs). Each sensor operates across distinct electromagnetic bands, spatial resolutions, and environmental operating envelopes.
The primary engineering challenge in multi-modal edge perception is achieving sub-microsecond temporal synchronization and precise spatial registration across disparate sensor streams. If a camera image captured at timestamp T is fused with a LiDAR point cloud captured at timestamp T plus twenty milliseconds, spatial disparities introduce severe phantom velocity vectors and catastrophic localization drift during high-speed vehicle yaw maneuvers.
Edge compute hardware resolves this challenge through hardware-level PTP (Precision Time Protocol, IEEE 1588v2) synchronization. A central grandmaster clock distributes synchronized sub-microsecond timestamps across all sensor interfaces via Gigabit Ethernet. Hardware trigger pulses fire camera image sensor shutters and LiDAR laser pulse arrays synchronously. Sensor data is serialized over automotive Ethernet (1000BASE-T1) directly into system memory utilizing Direct Memory Access (DMA), bypassing the CPU to eliminate interrupt latency.
Within the edge compute engine, sensor fusion occurs at the feature level (deep early fusion) rather than the object level (late fusion). Raw camera pixel arrays and spatial LiDAR point-cloud voxels are projected into a unified, metric 3D Bird’s-Eye-View (BEV) feature space through cross-attention transformer layers, enabling the autonomous platform to maintain an unyielding 360-degree environmental spatial representation regardless of rain, darkness, or optical sensor occlusion.
Distributed Peer-to-Peer Mesh Networks: V2X and Cooperative Swarm Autonomy
While localized onboard computation enables individual autonomous platforms to operate safely in isolation, true scalability, traffic optimization, and swarm coordination require platforms to collaborate dynamically through decentralized Vehicle-to-Everything (V2X) communication networks.
Traditional cellular telecommunications (4G LTE and non-standalone 5G) rely upon centralized cellular towers and core packet gateways. If two autonomous vehicles traveling in opposite directions toward an occluded intersection must negotiate right-of-way, transmitting messages through a cellular base station introduces unmanageable transmission latency and dependency on cellular coverage. In contrast, Cellular-V2X (C-V2X) direct communication (PC5 interface) and Dedicated Short-Range Communications (DSRC, IEEE 802.11p) operate over direct peer-to-peer radio frequency channels, bypassing cellular base stations completely to achieve ultra-reliable low-latency communication (URLLC) with sub-two-millisecond transmission latencies over distances of several hundred meters.
In industrial robotics, military reconnaissance swarms, and autonomous mining vehicles, platforms form ad-hoc dynamic wireless mesh networks. Utilizing distributed routing algorithms (such as Optimized Link State Routing, OLSR, or Better Approach To Mobile Adhoc Networking, B.A.T.M.A.N.), mesh nodes automatically establish self-healing, multi-hop routing paths. If an intermediate communication node is physically damaged or obstructed by geological terrain, the mesh network dynamically recalibrates routes within milliseconds, maintaining swarm connectivity without centralized infrastructure.
Decentralized V2X mesh communication enables cooperative perception (collective perception). A vehicle equipped with advanced long-range LiDAR can broadcast compressed vector representations of occluded obstacles (such as a child stepping out behind a parked truck) to trailing vehicles over V2X broadcast channels. Recipient vehicles integrate this remote sensor data into their local spatial planners, braking smoothly before their own onboard optical sensors can physically observe the obstacle.
Multi-Access Edge Computing (MEC) Infrastructure and Roadside Units (RSUs)
To bridge the computational gap between resource-constrained onboard mobile computers and distant hyperscale cloud servers, enterprise autonomous architectures deploy intermediate roadside Multi-Access Edge Computing (MEC) nodes and intelligent Roadside Units (RSUs).
MEC nodes are micro-datacenters deployed at cellular base stations, traffic intersections, highway gantries, and industrial warehouse docking bays. Equipped with multi-GPU server clusters, high-capacity solid-state storage, and fiber-optic backbones, MEC nodes possess computational capabilities far exceeding onboard vehicle hardware while residing within one to two optical hops of mobile platforms, delivering guaranteed network latencies under five milliseconds.
Intelligent RSUs mounted above urban intersections ingest continuous optical, thermal, and radar sensor feeds from elevated, bird’s-eye viewpoints. By executing localized object tracking and trajectory prediction, RSUs compute holistic intersection traffic flow dynamics. When an emergency vehicle approaches, the RSU dynamically orchestrates traffic signal phase transitions while simultaneously transmitting microsecond priority trajectory reservations to autonomous civilian vehicles over 5G sidelink channels.
MEC infrastructure also offloads computationally intensive, non-safety-critical background workloads from mobile autonomous agents. While onboard computers focus exclusively on immediate physical control and reactive collision avoidance, intermediate MEC nodes handle heavy global route optimization, dynamic high-definition (HD) map vector tile rendering, and regional weather radar assimilation, pushing updated localized vector layers to passing platforms via low-latency wireless bursts.
Decentralized Consensus and Spatial Coordination in Robotic Swarms
When hundreds of autonomous agents—such as automated guided vehicles (AGVs) in an e-commerce fulfillment warehouse or autonomous drones inspecting agricultural acreage—operate concurrently in shared physical space, the system requires decentralized coordination to prevent spatial bottlenecks, deadlocks, and physical collisions.
Centralized fleet dispatch servers introduce single points of failure and severe computational bottlenecks as fleet sizes scale past several thousand units. Modern autonomous architectures replace centralized dispatch with decentralized swarm consensus algorithms rooted in distributed state machines and computational geometry.
Robotic swarms employ distributed spatial reservation protocols based on Spatio-Temporal Occupancy Grids. Rather than relying on a central server to assign waypoints, autonomous agents broadcast their intended four-dimensional space-time trajectories (x, y, z coordinates over discrete future time horizons) to local mesh peers. Swarm nodes evaluate these trajectories locally utilizing velocity obstacle algorithms and decentralized consensus mechanisms (such as lightweight Raft or gossip-based state synchronization), negotiating optimal conflict-free spatial reservations through automated peer-to-peer auction mechanics.
Furthermore, distributed Simultaneous Localization and Mapping (Multi-Agent SLAM) allows swarms to collaboratively map unknown environments. Each robot extracts keyframe visual and geometric landmarks from its local environment, compresses them into invariant bag-of-words descriptors, and broadcasts them across the peer mesh. When two robots observe the same physical landmark from different vantage points, a distributed loop closure is detected, allowing the swarm to dynamically merge individual coordinate systems into a single, global reference map without centralized computing.
Data Curation and Intelligent Edge-to-Cloud Asynchronous Synchronization
A commercial autonomous vehicle fleet generates an astronomical volume of raw telemetry: a single development vehicle equipped with eight 4K cameras, five LiDARs, and radar arrays produces between five and twenty terabytes of raw data per eight-hour operational shift. Transmitting this raw data flood over cellular networks to central clouds is economically impossible and telecommunication-infeasible.
Modern edge architectures implement intelligent edge data curation. Rather than streaming raw sensor feeds continuously, edge platforms execute real-time trigger evaluation engines that identify and retain only high-value, novel operational data. Autonomous compute nodes run shadow perception models in the background, comparing real-time inference predictions against actual vehicle path outcomes.
When a discrepancy or edge-case anomaly occurs—such as an unclassified physical obstacle, sudden hard braking intervention, severe weather condition, or near-miss trajectory conflict—the edge curation engine buffers the surrounding thirty seconds of high-fidelity multi-modal sensor logs into local non-volatile storage. Routine, uninteresting driving data (such as thousands of miles of uneventful highway driving) is discarded or compressed into lightweight statistical operational metrics.
Curated anomaly payloads are asynchronously uploaded to enterprise cloud datacenters when vehicles return to base depots over high-throughput Wi-Fi 7 or 10Gbps optical docking ports. In the cloud, these curated edge cases are ingested into automated continuous learning pipelines, generating targeted synthetic data variations and retraining perception models before deploying updated, quantized weights back to the edge fleet via secure Over-The-Air (OTA) firmware updates.
Time-Sensitive Networking (TSN) and Deterministic In-Vehicle Ethernet Fabrics
As autonomous platforms evolve from distributed federated electronic control units (ECUs) toward centralized zonal computing architectures, legacy automotive networking buses—specifically Controller Area Network (CAN) and Local Interconnect Network (LIN)—reach their absolute physical throughput and latency limits. With CAN-FD maxing out at five to eight megabits per second, transmitting multi-camera 4K uncompressed raw video streams and high-density LiDAR data requires a radical physical layer upgrade to Time-Sensitive Networking (TSN) over Automotive Ethernet (1000BASE-T1 and 10GBASE-T1).
TSN, standardized under IEEE 802.1, transforms standard non-deterministic Ethernet into a guaranteed, low-jitter deterministic communications backbone. Central to this transformation is the IEEE 802.1Qbv Time-Aware Shaper (TAS). TAS divides network transmission time into repeating, microsecond-accurate time slots governed by a global synchronized clock (IEEE 802.1AS). Safety-critical perception and steering packets are assigned exclusive, protected time windows during which all non-critical best-effort traffic is completely blocked at switch ingress queues, guaranteeing zero buffer contention and sub-microsecond transit latency across the vehicle wiring harness.
Complementing TAS, IEEE 802.1CB Frame Replication and Elimination for Reliability (FRER) delivers seamless hardware fault tolerance. Critical trajectory and braking packets are duplicated at the source and transmitted simultaneously across physically disjoint, redundant Ethernet network paths. The destination edge controller ingests the first packet that arrives and discards the duplicate. If a wiring harness is severed or an intermediate network switch suffers an electrical failure, zero packets are lost, ensuring continuous deterministic control during catastrophic physical disruptions.
Spatial 3D Occupancy Networks and Voxelized Temporal Fusion at the Edge
Early generations of autonomous perception systems relied upon 2D bounding boxes and heuristic object classifiers to detect standard traffic elements: automobiles, pedestrians, and cyclists. However, this classical approach suffers catastrophic failure modes when encountering open-vocabulary or out-of-distribution road obstacles: overturned cargo, construction debris, fallen tree branches, or unusual animal species that do not match predefined training labels.
Modern autonomous edge architectures overcome this fundamental limitation by executing Spatial 3D Occupancy Networks. Inspired by medical computed tomography, occupancy networks divide the three-dimensional physical volume surrounding the vehicle into millions of discrete volumetric pixels, termed voxels (typically spanning twenty to fifty centimeters per voxel edge). Rather than asking what an object is, the neural network predicts whether each specific 3D voxel in space is physically occupied or free, alongside its instantaneous 3D velocity vector (occupancy flow).
Executing 3D occupancy networks within the strict computational budgets of edge hardware demands temporal feature caching and cross-attention spatial transformers. Multi-camera feature maps extracted by efficient convolutional backbones (such as RegNet or EfficientNet) are unprojected into 3D voxel space utilizing camera intrinsic and extrinsic calibration matrices. Temporal cross-attention layers fuse current voxel states with historical voxel features from preceding frames, resolving occlusions and estimating precise velocities of moving obstacles even when momentarily hidden behind other vehicles.
Thermal Throttling Dynamics and Harsh Environmental Liquid Cooling Systems
A critical, frequently overlooked engineering challenge in autonomous edge computing is physical thermal management. High-performance autonomous compute platforms—operating dual high-end SoCs, multiple discrete FPGAs, and dense NPU accelerators—dissipate between two hundred and eight hundred watts of continuous thermal energy. Unlike enterprise servers operating in climate-controlled, air-conditioned datacenters, autonomous vehicle computers must operate reliably across extreme industrial temperature ranges (-40 degrees Celsius to +85 degrees Celsius ambient), exposed to intense solar radiant heating, dust, moisture, and intense vibrational shock.
If silicon junction temperatures exceed safe thermal operating thresholds (typically 100 to 105 degrees Celsius), modern microprocessors automatically engage thermal throttling: dynamically scaling down core clock frequencies and supply voltages to prevent permanent physical silicon damage. In general-purpose computing, thermal throttling merely degrades application speed; in autonomous robotics, a sudden forty percent reduction in clock speed causes neural inference loops to miss their deterministic deadlines, precipitating catastrophic control failures.
To prevent thermal throttling under peak ambient desert conditions, edge compute enclosures are engineered with hermetically sealed, IP67-rated aluminum chassis integrated directly into the platform’s active liquid cooling loop. Coolant fluid (a specialized water-ethylene glycol mixture or dielectric fluid) is pumped across micro-channel copper cold plates directly contacting processor integrated heat spreaders (IHS). Advanced thermal management software continuously monitors localized silicon temperature sensors, dynamically modulating coolant pump flow rates and fan speeds prior to heavy computational tasks, guaranteeing unyielding deterministic throughput without thermal degradation.
Federated Edge Learning and Privacy-Preserving Collaborative Adaptation
As autonomous fleets scale globally, continuous model improvement requires learning from edge-case driving scenarios encountered across millions of diverse geographic locations. However, centralizing high-resolution video streams from global fleets violates strict regional data privacy regulations (such as the European Union GDPR and California CCPA), which classify passenger faces and license plate numbers as protected personal identification data.
Federated Learning (FL) resolves this regulatory conflict by decentralizing the model training process itself. Instead of uploading raw sensor data to the cloud, the global foundational model is deployed to edge platforms. When an autonomous vehicle encounters novel road topologies or unusual environmental conditions, it executes local model training subroutines on its onboard NPU during nocturnal depot charging, calculating localized parameter gradients based on its unique daily experiences.
These local model weight updates (gradients) are scrubbed utilizing Differential Privacy algorithms—injecting calibrated mathematical Gaussian noise to ensure individual vehicle identities or specific geographic locations cannot be reverse-engineered from parameter distributions. The encrypted weight updates are transmitted to a central aggregation server, which combines thousands of global updates using Federated Averaging (FedAvg) into an improved global model. This privacy-preserving collaborative loop enables planetary autonomous fleets to continuously evolve collective intelligence without ever compromising individual passenger privacy.
Power-Aware Dynamic Frequency Scaling and Energy Harvesting in Aerial Edge Nodes
In uncrewed aerial vehicles (UAVs), solar-powered stratospheric pseudo-satellites, and miniature autonomous exploration drones, electrical power constitutes the ultimate non-negotiable operational constraint. Unlike ground vehicles with massive hundreds-of-kilowatt-hour battery packs, an aerial drone’s total payload weight and flight endurance are strictly limited by battery mass. Every watt consumed by onboard compute silicon directly subtracts from propeller thrust and flight duration.
To maximize mission endurance, aerial edge compute platforms implement aggressive Power-Aware Dynamic Voltage and Frequency Scaling (DVFS) paired with Context-Adaptive Computation. Rather than executing multi-sensor transformer perception pipelines at maximum frame rates continuously, the edge operating system dynamically modulates compute clock speeds based on operational flight regime and environmental risk.
During high-altitude, open-sky cruising where obstacle density is virtually zero, the system throttles vision inference from thirty frames per second down to five frames per second, shutting down non-essential NPU tensor cores using clock-gating and power-gating subroutines, reducing compute power draw from eighty watts to less than twelve watts. Conversely, when the drone descends into complex urban canyons, dense tree canopies, or GPS-denied environments, the flight controller instantly ramps processor frequencies to peak turbo states within microsecond switching latencies, prioritizing maximum sensory perception over energy conservation.
Furthermore, autonomous aerial edge nodes integrate hybrid energy harvesting interfaces. Micro-controllers coordinate real-time power distribution between high-efficiency gallium arsenide (GaAs) solar cell arrays, regenerative aerodynamic propeller braking during descent, and lithium-sulfur energy storage cells. Power-aware scheduling algorithms evaluate ambient solar flux against predicted trajectory wind resistance, ensuring that edge neural processing dynamically matches available harvested energy reserves throughout multi-day continuous autonomous flight missions.
Emerging neuromorphic edge processors—mimicking biological neural spike timing and event-driven synaptic signaling—represent the frontier of ultra-low-power aerial perception. Unlike traditional synchronous vision sensors that capture entire frames thirty times per second, bio-inspired neuromorphic event cameras (such as dynamic vision sensors) transmit data only when individual pixels detect changes in scene luminance. When paired with asynchronous neuromorphic spiking neural network (SNN) silicon, event-based edge processing slashes optical processing latency to sub-millisecond ranges while operating within milliwatt power envelopes, enabling microscopic bio-mimetic drones to navigate chaotic aerodynamic turbulence and dodge ultra-fast moving obstacles with insect-like agility.
Security and Fault Tolerance at the Operational Edge: Zero Trust and Physical Tamper Resistance
Deploying compute silicon and sensitive decision-making algorithms directly into field environments introduces severe cybersecurity and physical tamper vulnerabilities. Unlike servers enclosed in biometric-secured datacenters, edge nodes on autonomous vehicles, drones, and utility stations are physically accessible to malicious actors and operate in hostile physical environments.
Edge cybersecurity requires an uncompromising Hardware Root of Trust (RoT). Silicon architectures must incorporate cryptographic secure elements and Trusted Platform Modules (TPM) that enforce Measured Boot and Secure Boot sequences. From the initial bootloader execution in immutable ROM through hypervisor initialization, every firmware binary and operating system kernel is cryptographically validated against manufacturer public keys stored in one-time-programmable silicon fuses. If an attacker attempts to inject malicious firmware or tamper with kernel memory, the secure enclave halts the processor instantly, preventing the autonomous agent from initiating physical movement.
Physical tamper resistance is enforced through active cryptographic memory encryption. Memory controllers on automotive edge processors (such as AMD SEV or Intel TME) encrypt all data traveling across the high-speed DDR memory bus utilizing AES-128 or AES-256 hardware engines. Even if an attacker physically probes high-frequency memory bus traces with oscilloscopes or cryogenic memory dump techniques, they extract only encrypted noise, protecting proprietary neural network model weights and cryptographic keys.
Across external network interfaces, edge platforms implement Zero Trust Network Architecture (ZTNA). Every incoming V2X message, roadside unit broadcast, and sensor bus communication is treated as inherently untrusted. Communications are mutually authenticated via mutual TLS (mTLS) with hardware-backed digital certificates, and incoming messages are subjected to deep packet semantic validation to prevent sensor spoofing, GPS denial, and distributed denial-of-service (DDoS) attacks.
Functional Safety and Redundancy Architecture: ASIL-D and Dual-Channel Fail-Operational Design
In safety-critical autonomous operations, hardware failure is not an unexpected anomaly; it is an inevitable physical certainty. Silicon chips can experience dielectric breakdown, memory cells can suffer single-event upsets (SEU) from cosmic radiation, and optical sensors can be blinded by road debris. Autonomous systems must be engineered with fail-operational redundancy to guarantee safe physical operation even following catastrophic internal hardware destruction.
Automotive and robotics safety standards (such as ISO 26262 ASIL-D and IEC 61508 SIL-3) mandate dual-channel or triple-modular redundant (TMR) architectures for mission-critical autonomy. High-end autonomous edge systems incorporate two completely independent, physically isolated compute channels: a Primary Autonomy Compute Channel and a Secondary Fallback Safety Channel, each equipped with dedicated power supplies, cooling loops, and sensor feeds.
The primary compute channel executes high-resolution perception, deep neural trajectory generation, and multi-sensor fusion. Concurrently, the independent fallback safety channel—often operating on diverse silicon architectures (such as lockstep ARM Cortex-R real-time cores) and executing deterministic rule-based physics models rather than deep neural networks—continuously monitors primary channel outputs.
Both channels communicate across isolated high-speed inter-processor communication buses, continuously exchanging heartbeat tokens and trajectory safety envelopes. If the primary compute engine suffers a hardware lockup, memory fault, or abnormal thermal shutdown, hardware watchdogs trigger seamless sub-millisecond fail-over to the safety channel. The fallback controller executes an immediate Minimal Risk Maneuver (MRM), smoothly pulling the vehicle over to the road shoulder or bringing an industrial robotic arm to an immediate controlled stop without human intervention.
To establish standardized engineering architectures for autonomous edge computing deployments across varying operational domains, systems architects utilize structured technical benchmark matrices. These matrices systematically map autonomous application tiers to latency limits, computational workloads, hardware silicon profiles, and communication protocols.
The following comprehensive comparative engineering matrix provides an authoritative technical blueprint evaluating primary autonomous edge computing tiers and deployment profiles.
Comparative Engineering Matrix of Autonomous Edge Computing Tiers & Silicon Profiles
| Autonomous Computing Tier | Strict Latency Budget | Primary Computational Workloads | Hardware Silicon & Architecture Profile | Primary Networking & Bus Protocols |
|---|---|---|---|---|
| Onboard Safety-Critical (Tier 1) | < 10 milliseconds | Emergency collision avoidance; actuator control; lockstep safety monitoring | ASIL-D lockstep microcontrollers (Infineon AURIX, ARM Cortex-R52); hard RTOS | CAN-FD; FlexRay; Time-Sensitive Networking (TSN IEEE 802.1Qbv) |
| Onboard Neural Perception (Tier 2) | 10 – 30 milliseconds | Multi-camera BEV transformers; 3D LiDAR point cloud voxelization; SLAM localization | Heterogeneous automotive SoCs (NVIDIA DRIVE Thor, Qualcomm Ride); 200-2000 TOPS | Automotive Ethernet (1000BASE-T1 / 10GBASE-T1); PCIe Gen 5; MIPI CSI-2 |
| Peer-to-Peer Swarm Mesh (Tier 3) | 2 – 15 milliseconds | Cooperative perception; decentralized trajectory reservation; multi-agent SLAM | Dedicated C-V2X baseband modems; embedded software-defined radios (SDRs) | C-V2X Direct PC5; DSRC IEEE 802.11p/bd; B.A.T.M.A.N. dynamic mesh routing |
| Roadside MEC Unit (Tier 4) | 5 – 25 milliseconds | Holistic intersection flow control; bird’s-eye sensor aggregation; local HD map updates | Ruggedized edge server clusters; multi-GPU inference racks; 400-800W power draw | 5G NR Sidelink; fiber-optic Ethernet backhaul; gRPC / Protocol Buffers |
| Depot & Cloud Backbone (Tier 5) | Asynchronous (> 1 sec) | Fleet-wide anomaly learning; synthetic simulation generation; foundational retraining | Hyperscale cloud clusters; high-throughput distributed NVMe storage fabrics | Wi-Fi 7 depot docking; 100GbE optical datacenter fabric; Apache Kafka / S3 |
Deploying these structured edge computing architectures enables autonomous platforms to achieve unassailable operational safety, sub-millisecond determinism, and planetary-scale fleet coordination. For technical standards on edge computing, automotive functional safety, and real-time robotic networking, systems engineers consult authoritative international organizations including the International Organization for Standardization Autonomous Vehicle Standards and the IEEE Computer Society Edge Computing Repository. Additional automotive safety benchmarks can be accessed through the SAE International Automated Driving System Technical Committee, alongside telecommunications specifications curated by the 3GPP Cellular V2X Technical Specifications Group and open-source autonomous robotics architectures from the ROS 2 Real-Time Robotics Foundation.
Frequently Asked Questions About Autonomous Edge Computing Architecture
What is the primary difference between edge computing and cloud computing in robotics?
Cloud computing centralizes data processing in remote datacenters, offering massive scalability but introducing transmission latencies of 50 to 200 milliseconds and requiring continuous network connectivity. Edge computing places specialized compute hardware directly onboard robots or at local roadside nodes, processing data in under ten milliseconds and ensuring autonomous operation even during complete network loss.
What is a deterministic real-time operating system (RTOS)?
An RTOS is an operating system designed to guarantee that computational tasks execute within mathematically bounded timeframes (worst-case execution time). Unlike general-purpose operating systems that prioritize average processing throughput, an RTOS guarantees zero task jitter and immediate pre-emptive scheduling for safety-critical control subroutines.
How does neural network quantization accelerate edge inference?
Quantization converts 32-bit floating-point weights and activation values into compact 8-bit or 4-bit integers. This reduces memory consumption by seventy-five percent, slashes memory bandwidth bottlenecks, and allows specialized NPU tensor cores to execute integer multiply-accumulate operations up to four times faster without sacrificing accuracy.
What role does C-V2X direct communication play in autonomous fleets?
C-V2X (Cellular Vehicle-to-Everything) direct PC5 communication allows vehicles to exchange data directly with adjacent vehicles and roadside infrastructure over peer-to-peer radio frequencies without routing through cellular towers. This achieves sub-two-millisecond latency for cooperative collision avoidance and real-time swarm maneuvering.
What is cooperative perception in autonomous vehicle swarms?
Cooperative perception allows multiple autonomous vehicles to share compressed sensor representations of their surrounding environments over peer-to-peer networks. This enables vehicles to see through obstacles, around blind corners, and past large trucks by viewing the environment through the sensors of neighboring vehicles.
What is an intelligent Roadside Unit (RSU)?
An RSU is an edge-connected computing and sensor module mounted on traffic poles or highway gantries. RSUs monitor high-density intersections using elevated cameras and radars, computing global traffic dynamics and broadcasting safety warnings to passing autonomous platforms to prevent intersection collisions.
How does hardware-level PTP sensor synchronization work?
PTP (Precision Time Protocol, IEEE 1588v2) synchronizes the internal clocks of cameras, LiDARs, radars, and compute engines to within sub-microsecond precision over Ethernet cables. This ensures that sensor frames captured by different devices represent the exact same instant in physical time, preventing spatial blur during high-speed sensor fusion.
What is fail-operational architecture in autonomous systems?
Fail-operational architecture guarantees that if a primary computer or sensor experiences a catastrophic physical failure, an independent, redundant backup safety channel takes control instantly. The backup system executes a minimal risk maneuver to bring the vehicle to a safe stop without human intervention.
How do edge systems filter and curate data for cloud training?
Instead of streaming terabytes of routine footage, edge systems run intelligent trigger algorithms that identify rare anomalies, near-miss events, or perception errors. Only the high-value sensor logs surrounding these edge cases are recorded and uploaded to the cloud for model retraining, optimizing bandwidth and storage costs.
Autonomous Edge Computing Synthesis and the Planetary Robotics Horizon
Edge computing is the indispensable technological catalyst transforming autonomous systems from controlled laboratory prototypes into ubiquitous, real-world physical reality. By synthesizing deterministic real-time operating kernels, heterogeneous neural acceleration silicon, sub-microsecond sensor synchronization, and decentralized peer-to-peer mesh networking, autonomous edge architectures liberate intelligent machines from the tether of centralized cloud latency. As these resilient, self-contained computational fabrics continue to proliferate across roadways, manufacturing floors, oceanic fleets, and planetary exploration swarms, they establish the unassailable foundation for a safe, interconnected, and fully autonomous physical civilization.